Per-task cost attribution means stating the exact expense incurred to complete a single unit of work across every token, tool invocation, retry, and external system involved. This approach differs from calculating average costs per API call or dividing a monthly vendor invoice by total volume. It captures the true end-to-end trace of one specific task, distinguishing its financial impact from every other transaction handled that day.
Why Can't Most Organizations Produce This Number Today?
Three consistent operational gaps prevent companies from generating this metric. First, standard AI platforms log expenses at the individual model call level rather than the task level, scattering expenses across disconnected entries when a workflow involves multiple reasoning steps, tool calls, and retries.
Second, most systems lack a unified tracking identifier that accompanies a task across every stage, forcing teams to perform time-consuming manual correlation to reconstruct costs retroactively.
Third, few engineering groups have prioritized building this instrumentation because the absence of this data creates diffuse friction, appearing as a vague feeling of overspending rather than an immediate blocking issue with a designated owner.
What Is the Difference Between Per-Task Cost and Average Cost Per Call?
Average cost per call represents a basic metric that provides minimal insight. Calculated by dividing total spend by total model invocations, it treats a cheap, routine data lookup as equivalent to an expensive, multi-step reasoning pass. Per-task cost preserves the operational variance that average metrics flatten out. It highlights when a specific execution costs forty times more than a standard run, allowing teams to investigate root causes instead of viewing a blended number that obscures inefficiencies.

forecasts over 5x increase in AI inference costs per agentic workflow through 2028, as growing workflow complexity outpaces improvements in token economics.
The statistic above reinforces the case for per-task cost attribution, which is to evaluate the complete execution path rather than treating an individual model call as the unit of work.
How Do You Build Per-Task Cost Attribution?
Building per-task attribution requires generating a single tracking identifier at the beginning of a workflow and propagating it through every subsequent operation, including model calls, tool executions, retries, and sub-agent handoffs. Every subsystem logs its incurred costs directly against that shared ID. Aggregating all financial entries tied to that specific tag reveals the true, traced cost of the completed task rather than a rough approximation.
While this requires dedicated instrumentation, the process mirrors distributed tracing practices that engineering teams already use for latency monitoring, applying those same principles to financial management.
What Does Per-Task Visibility Unlock Once You Have It?
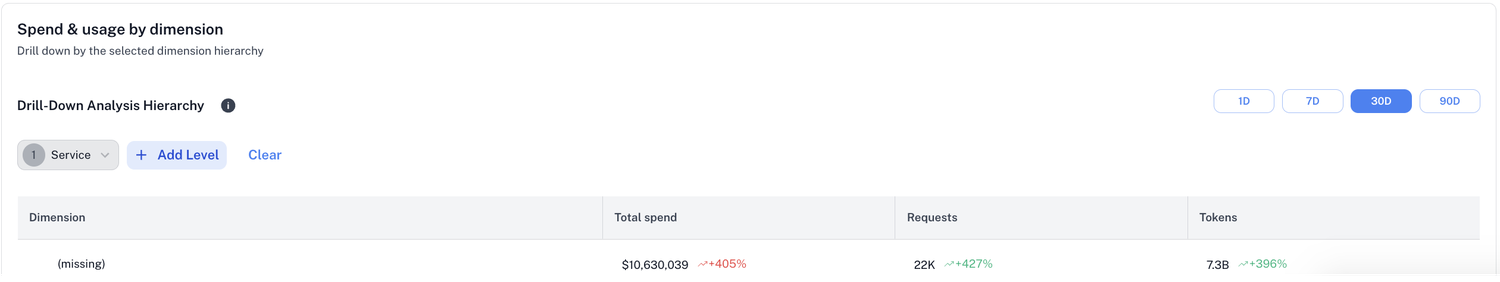
Establishing per-task visibility serves as the core foundation for advanced AI financial strategies:
- Autonomy Optimization: Locating the break-even point on the cost-to-autonomy curve requires comparing exact unit costs across different automation levels.
- Proactive Guardrails: Setting actionable spend limits relies on knowing expected task costs so system anomalies can trigger automated alerts or pauses.
- Accurate Chargeback: Allocating expenses back to specific business units demands tracing every operation directly to the initiating workflow and team.
- Realistic ROI Modeling: Evaluating true agent returns requires accounting for total execution expenses, including error recovery and retries.
Key Takeaways
Organizations that cannot determine the full end-to-end cost of a specific task cannot effectively optimize agent autonomy, establish real-time spend guardrails, execute precise chargeback, or calculate accurate ROI. These capabilities all depend on the exact same underlying metric. Implementing request tracing to capture per-task cost data once resolves these related financial challenges across the entire operational stack.