New blog: Do you know what your Claude Code is doing? (Part 2)   Read the post →

FinOps, Observability and Optimization for your AI and Data

Autonomous agents that find wasted spend, slow queries and bad data across your LLMs, data warehouses, and then fix them.
See every AI dollar, and how much of it you can recover
AI spend · last 30 days
Live
$2.5M
+12% vs prior 30 days
Forecast · next 30d
$2.1M
Spend per call
$29.93
Active users
620
Requests
83K
Failure rate
12.0%
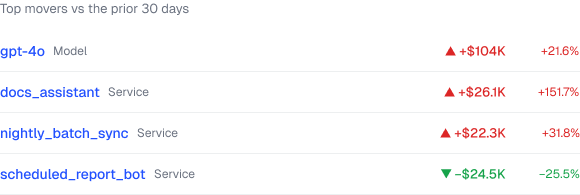
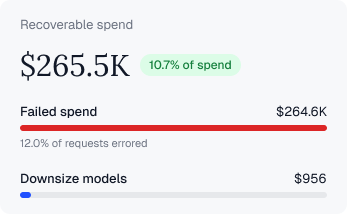
Top moversRecoverable spend
See what every agent costs, and which ones are growing fastest
Spend by agent · last 30 days
$2.6M
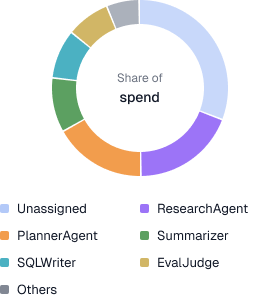
Share of spend by agent
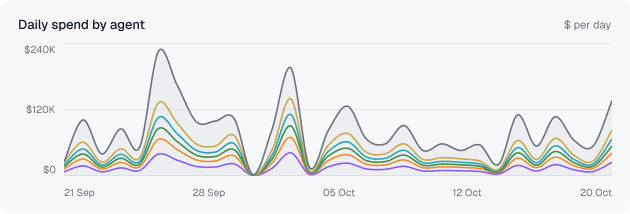
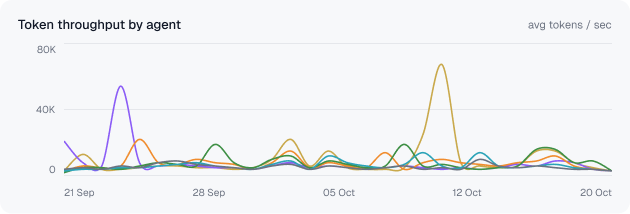
Daily spend by agentToken throughput by agent
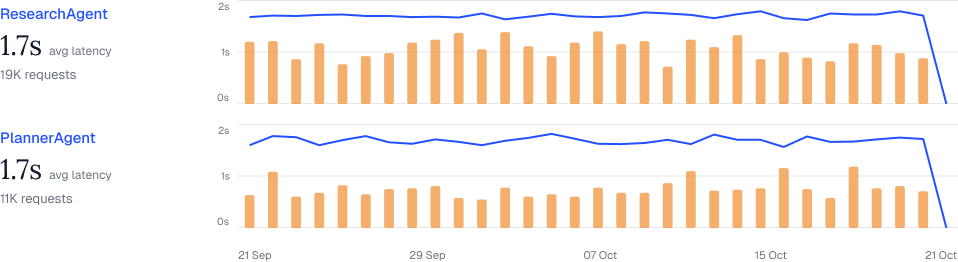
See how fast each agent responds, and how often it reuses cached work
Agent performance · last 30 days
Avg latency
Cache hit rate
30K
agent requests
2 agents
Latency and cache hit rate per agent
Write better and efficient code
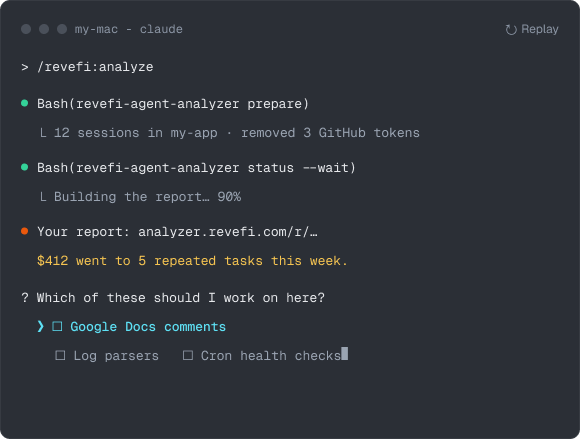
Claude Code terminal
Repeated work this week
$412

went to 5 tasks Claude Code redid in every session. The top three:
Resolving Google Docs comments one at a time
$176
Writing a new log parser for every investigation
$79
Checking cron health by hand
$68
Fewer turns
Lower bills
Faster sessions
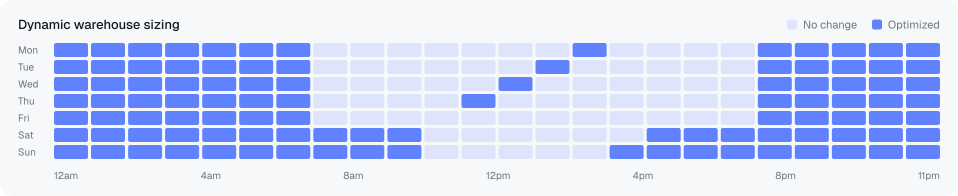
See every warehouse right-sized, hour by hour
Warehouse performance report · Adhoc_Workload_WH
$44,369.52
annualized savings
54% reduction
Avg query execution
17 s
was 25.13 s
Avg queuing time
1 s
was 3.71 s
Queries
54,504
was 37,203
Credits used weekly
264.42
at $3 per credit
Dynamic warehouse sizing heatmap: hours optimized vs no change across the week
Gartner Cool Vendor 2025 badge
Recognized as a
Gartner® Cool Vendor
2025
Trusted by global brands

Built for every AI model, Agent and every database you run

One platform. Reduces cost, improves performance and quality of your stack.
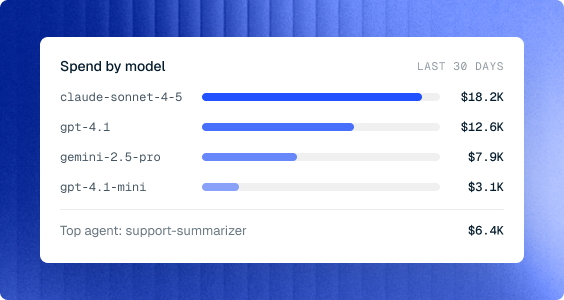
AI FinOps widget showing spend by model

AI FinOps & Observability

For every LLM and Agent

Observability and FinOps for LLMs and agents, with user, agent and model attribution across OpenAI, Anthropic and Google.

Granular
Cost attribution
Full
Visibility per user, agent and model
Zero
code changes to set up
Explore AI FinOps →
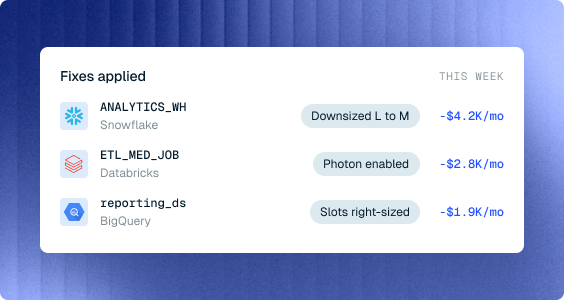
AI DBA widget showing fixes applied to Snowflake, Databricks and BigQuery

AI DBA

For every database you manage

Tunes warehouses, fixes slow queries and reclaims idle spend across Snowflake, Databricks, BigQuery and Redshift.

30-70%
Lower data platform spend
10x
Operational efficiency
5 min
To first results
Explore AI DBA →

Maximize the ROI of your AI, agents and data

The problems teams bring to us, and what changes once Revefi is running.

You are experiencing
Unknown Budget
Uncontrolled token usage.
Track Adoption
Trust issues with AI output.
Unpredictable Performance
Revefi impact
AI Observability
Full Visibility
AI Metering
Cost Control
AI Quality
Verified Truth
Works across
and Your model
You are experiencing
Blown Budget
Unpredictable compute costs.
Poor Data Quality
Inaccurate data & lack of trust.
Fire-Fighting
Constant operational issues.
Revefi impact
Reduce Data Cost
by 30–70%
Increase Efficiency
by 10×
Get Results
in 5 mins
Works across

It doesn't just flag the problem. It opens the ticket and the PR.

Revefi's AI agent and MCP server work inside Claude Code. Here it found an over-provisioned Databricks job, filed the Jira issue and opened a pull request with the fix.

Graviton3 nodes instead of m5d.large
Photon vectorized runtime
All checks passed, ready to merge
See it on your stack
Claude Code · ~/revefi/shasta-databricks
> Find the biggest Databricks saving and fix it
Revefi MCP: ETLMedJob is over-provisioned on m5d.large with the STANDARD runtime
✓ Created Jira issue TEST-416
✓ Opened PR #1 on revefi/shasta-databricks
TEST-416
IN PROGRESS
Optimize ETLMedJob cluster configuration with Photon runtime
ASSIGNEE  CLAUDE (BOT)   ·   LABELS  COST-OPTIMIZATION, DATABRICKS
dbc_bundle/resources/etl_med_job.yml
+6 -2
23
 
spot_bid_price_percent: 100
24
-
node_type_id: m5d.large
24
+
node_type_id: m7gd.large
25
+
driver_node_type_id: m7gd.large
31
+
spark_conf:
33
+
  spark.databricks.cluster.profile: singleNode
32
-
runtime_engine: STANDARD
36
+
runtime_engine: PHOTON
✓ All checks passed
Merge pull request
◀ ▶ ↻
Your workProjectsDashboards
KR
Projects / TEST / TEST-416
TEST-416
Optimize ETLMedJob cluster configuration with Photon runtime
Description

Updated ETLMedJob cluster configuration based on Revefi's cluster optimization experiment recommendations.

Configuration Changes:
  • Node type: m5d.large → m7gd.large (Graviton3)
  • Runtime: STANDARD → PHOTON (vectorized engine)
  • Added driver_node_type_id and spark_conf for single-node
Benefits:

Better performance and cost efficiency for Auto Loader streaming workloads.

Activity
C
Claude created this issue
Just now
C
Claude changed status to In Progress
Just now
◈revefi / shasta-databricksPR #1
[TEST-416][Part 1] Optimize ETLMedJob cluster config with Photon runtime and m7gd.large #1
● OpenClaude wants to merge into main from kr_optimize-etlmed-cluster
Conversation
Files changed
Checks
▾ dbc_bundle/resources/etl_med_job.yml
+6 −2 · YAML
⋯ 20 unchanged lines
21 first_on_demand: 1
22 zone_id: us-west-2d
23 spot_bid_price_percent: 100
24 − node_type_id: m5d.large
24 + node_type_id: m7gd.large
25 + driver_node_type_id: m7gd.large
26 cluster_log_conf:
27 volumes:
28 destination: /Volumes/revefi/default/logs
29 spark_env_vars:
30 PYSPARK_PYTHON: /databricks/python3/bin/python3
31 + spark_conf:
32 + spark.master: local[*, 4]
33 + spark.databricks.cluster.profile: singleNode
34 enable_elastic_disk: false
35 data_security_mode: DATA_SECURITY_MODE_DEDICATED
32 − runtime_engine: STANDARD
36 + runtime_engine: PHOTON
37 kind: CLASSIC_PREVIEW
38 is_single_node: true
⋯ 4 unchanged lines
✓ All checks passed

Customer stories

1 / 6
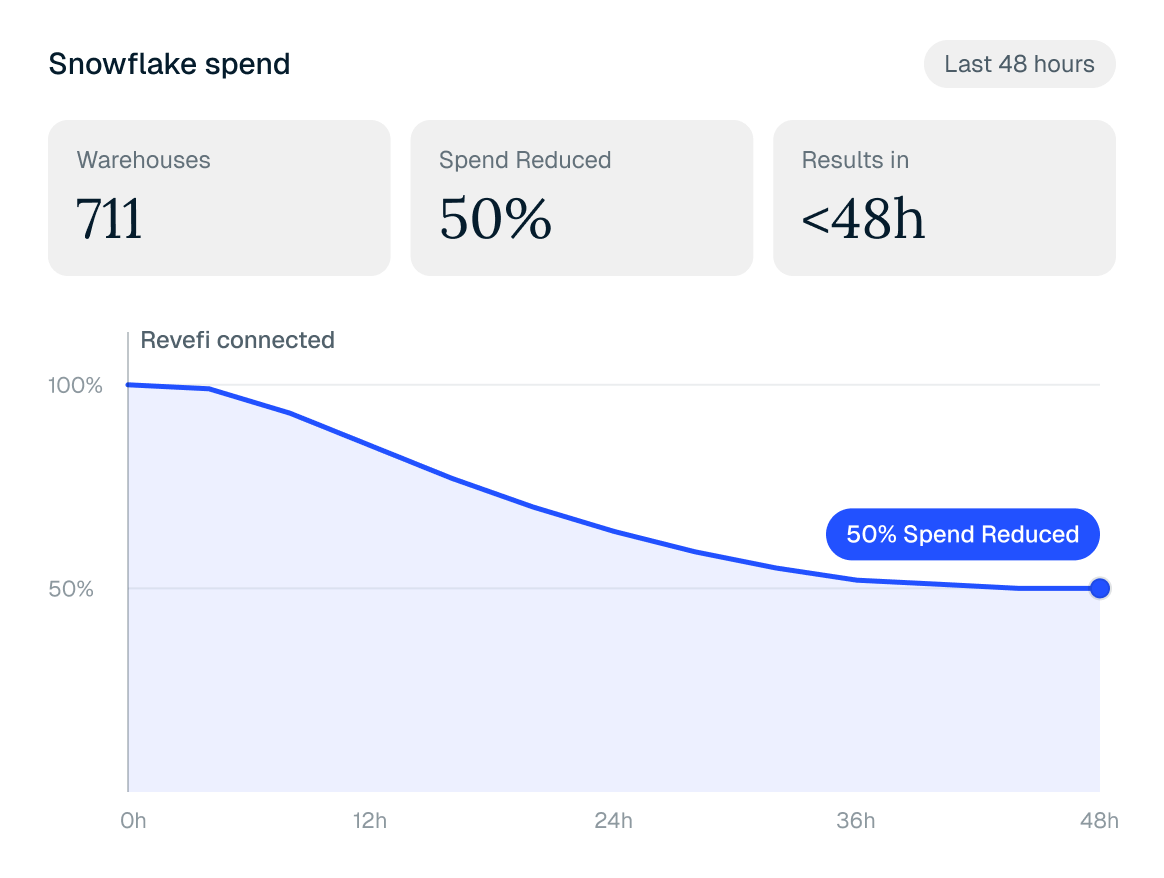
A Fortune 500 Insurer using Snowflake.
711
Snowflake Warehouses
50%
Spend Reduced
<48h
Results in <48 hours
Snowflake spend dropping 50% within 48 hours of connecting Revefi
A Fortune 1000 Insurtech company.
5 out of 5 stars
“With Revefi, the value of FinOps and Data Observability became clear within just a few months. They identified savings, improved quality and more than paid for themselves in no time.”
Louis DiModugno
Louis DiModugno
Global CDO
Fortune 1000 Company
Read Case Study ↗
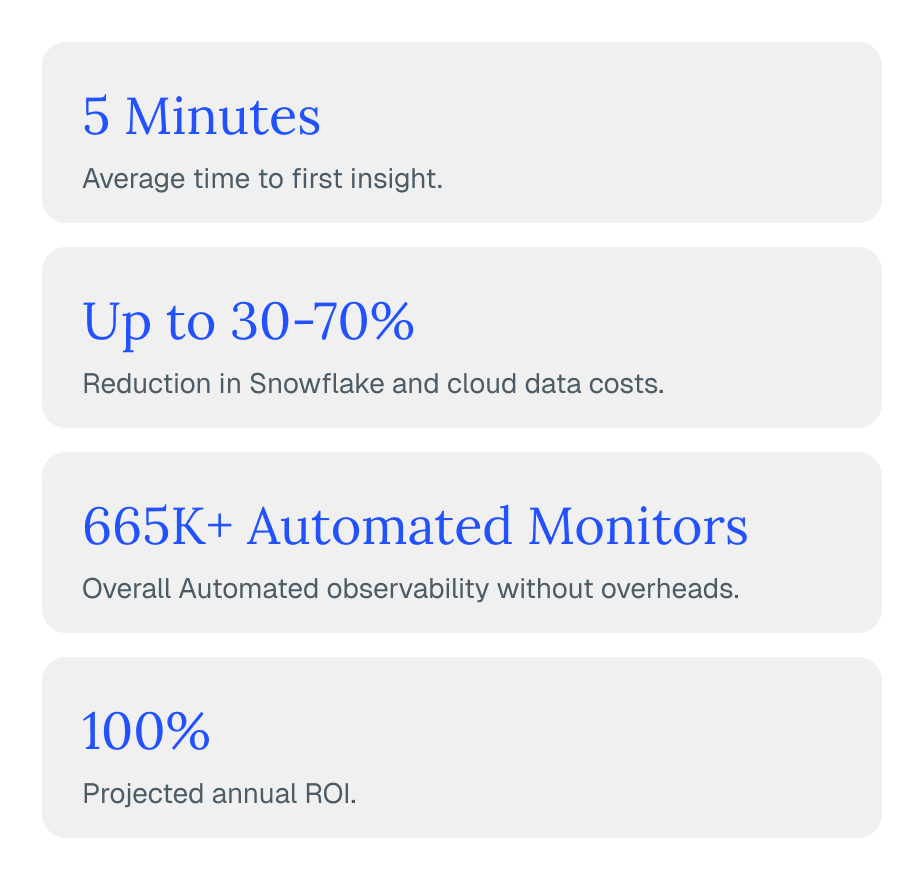
5 minutes to first insight, up to 30-70% lower cloud data costs, 665K+ automated monitors, 100% projected annual ROI
Healthcare provider using Snowflake.
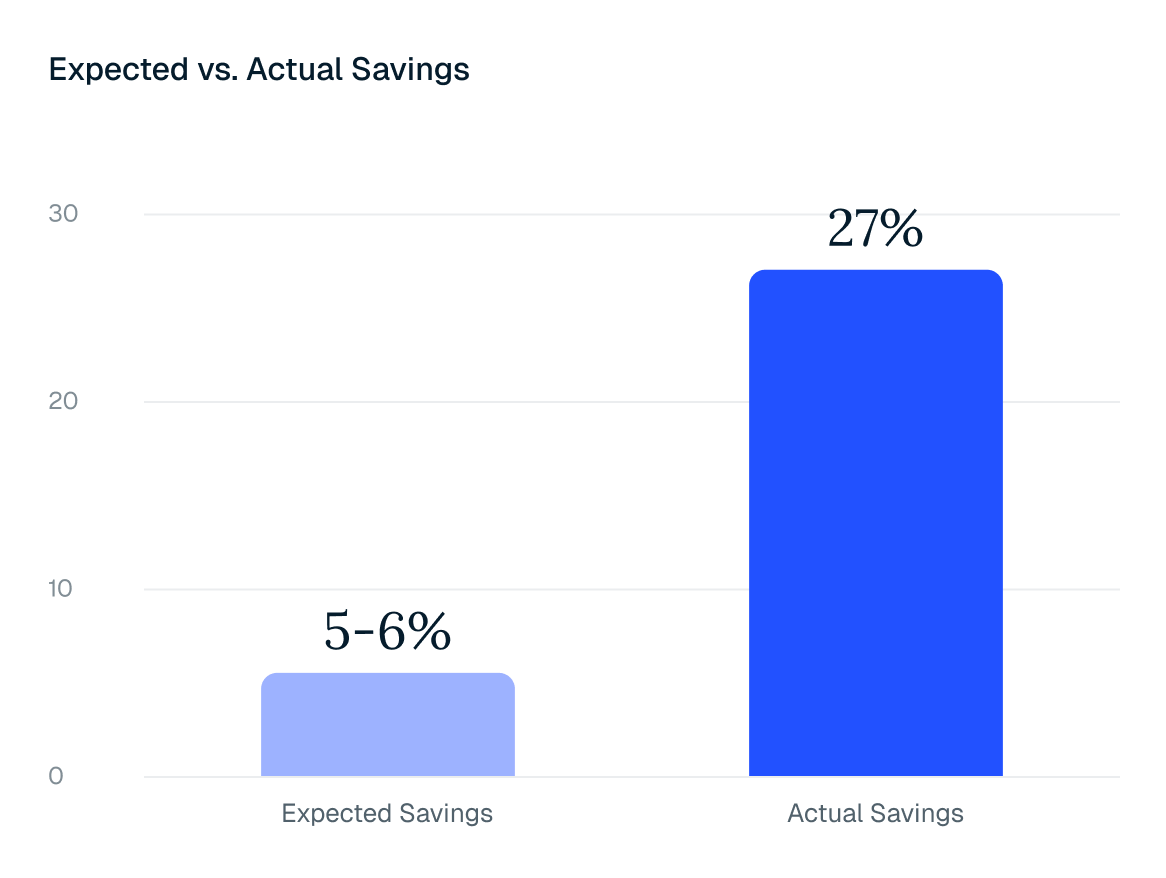
27%
Less Snowflake spend
5×
Beyond the 5–6% expected
3 Weeks
To deliver, start to finish
Bar chart: 5-6% expected savings versus 27% actual savings
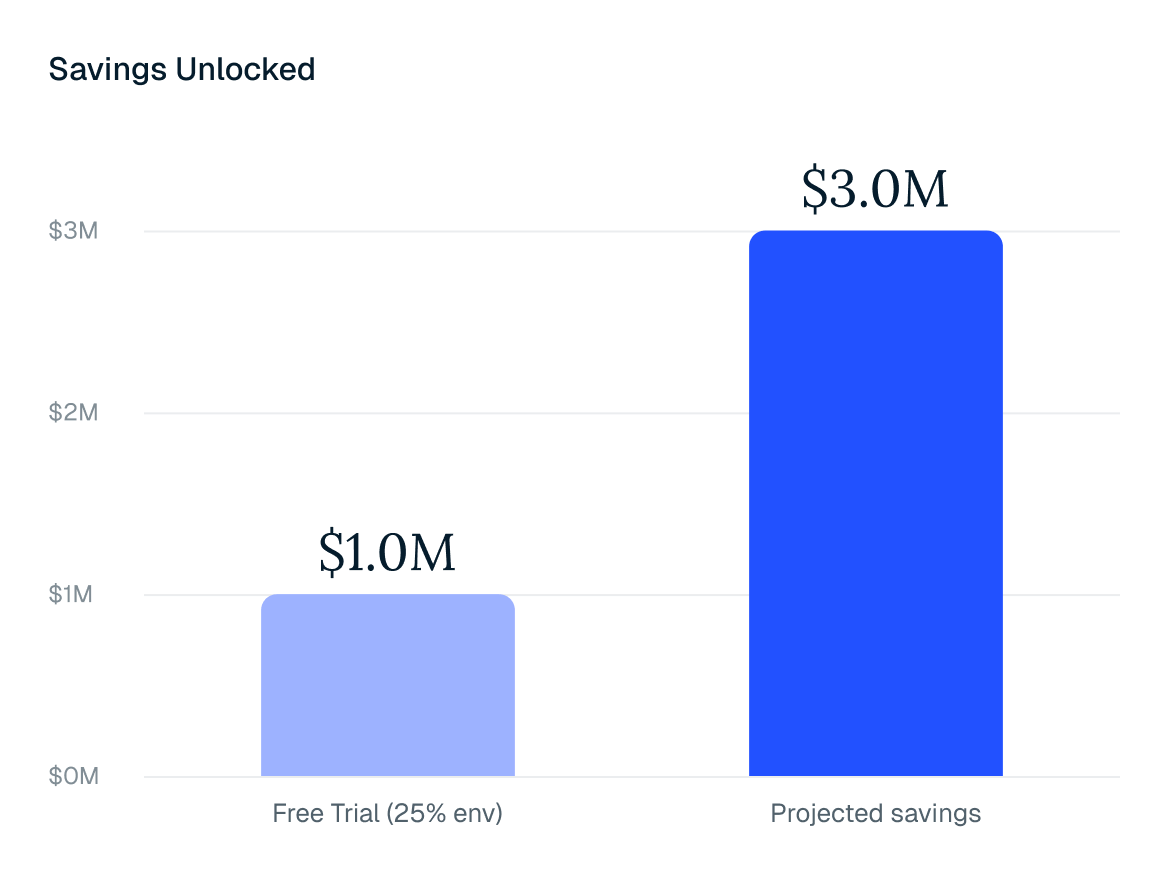
Fortune 200 Enterprise using Databricks.
~$1M
Saved during the free trial
25%
Of production covered so far
>$3M
Projected across all production
Bar chart: $1.0M saved in the free trial versus $3.0M projected savings
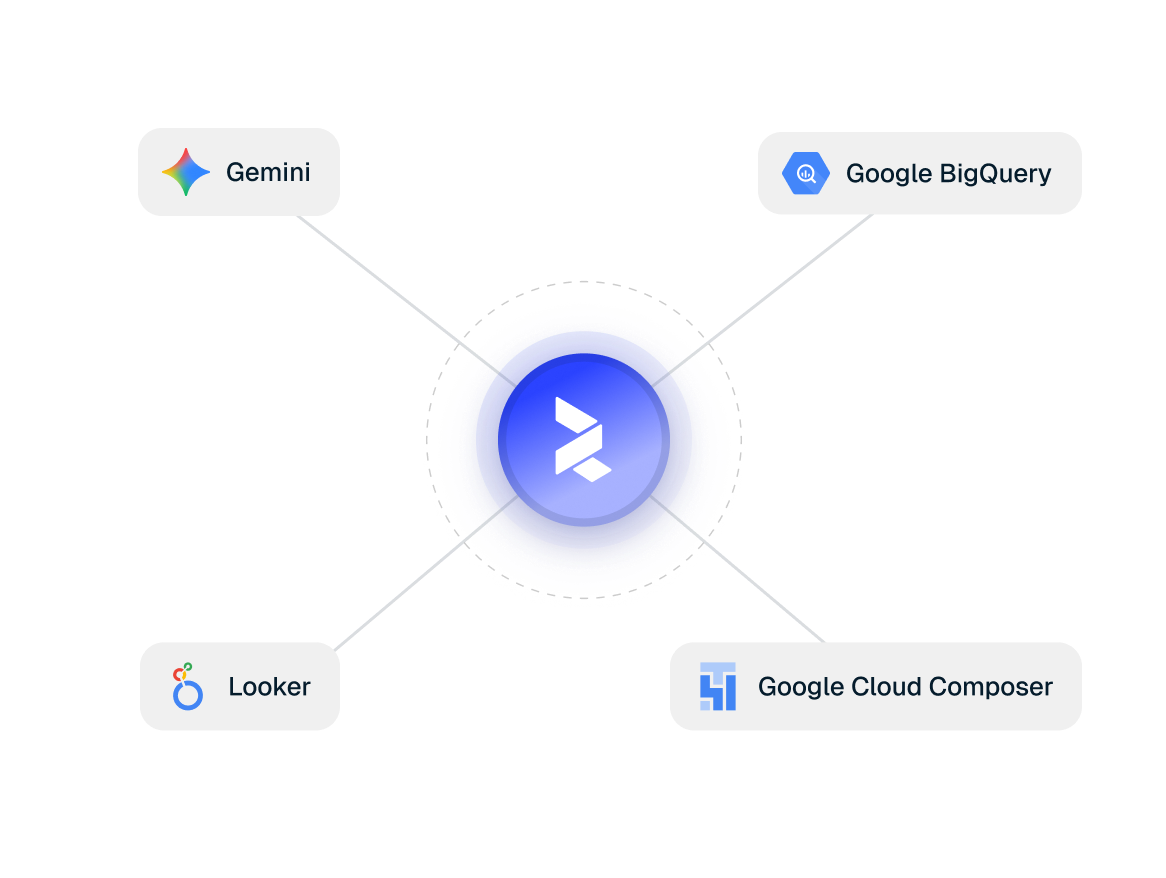
A Fortune 50 service provider, the largest BigQuery customer in the U.S.
100% Unified
All Data-SLAs and RCA
3x Increased
Interoperability between systems & tools
4 Platforms
In one interface: BigQuery, Looker, Composer & Gemini
Revefi connected to Gemini, Google BigQuery, Looker and Google Cloud Composer
Maximizing ROI of AI, F200 Enterprise.
8x
increase in AI spend in less than 4 months
25K+
users and increasing
200M+
requests monthly and increasing
10K+
AI services and increasing
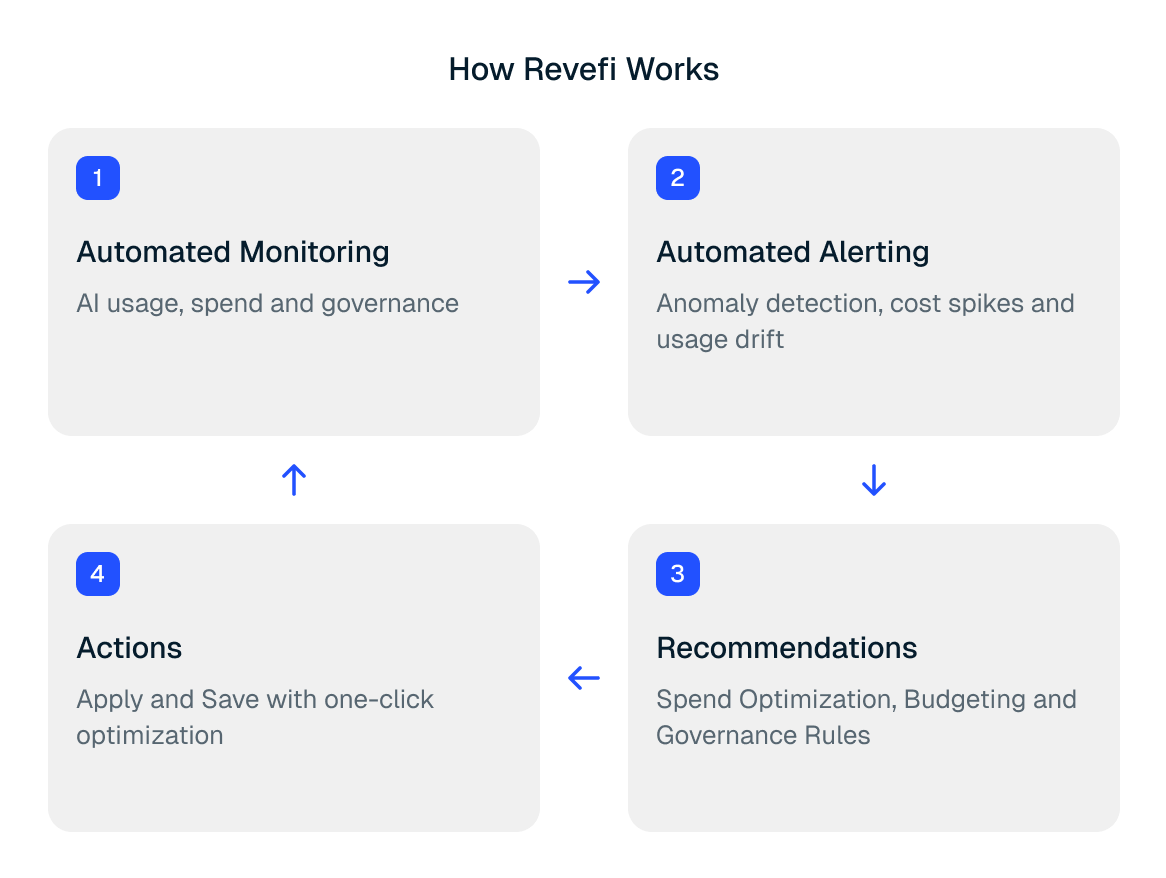
How Revefi works: automated monitoring, alerting, recommendations and one-click actions

What makes Revefi different?

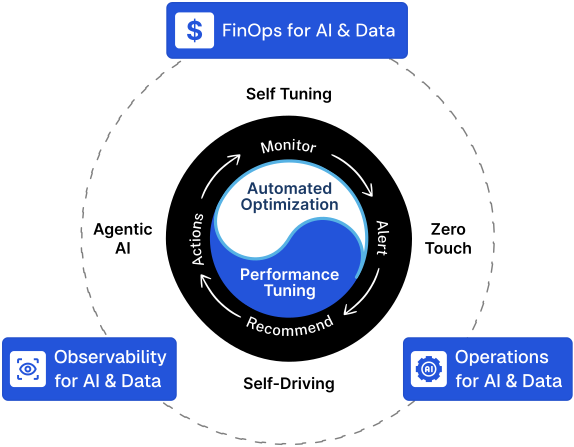
Most tools stop at the alert. Revefi runs the whole loop for you across AI and data: it monitors, alerts, recommends and acts, then keeps tuning on its own.

Self-tuning

Adjusts to workload shifts on its own.

Self-driving

Applies the fix, not just the alert.

Agentic AI

An agent on every model and warehouse.

Zero-touch

Live in 5 minutes, no code changes.

Revefi closed loop: monitor, alert, recommend and act across FinOps, observability and operations for AI and data

See what Revefi could save you.

See Revefi on your own stack in a demo, or estimate your savings first with our calculators for Snowflake, Databricks, Google BigQuery and AI.

Cost calculator
Monthly LLM and AI spend
$120,000
Estimated savings
$24K to $48K
a month
See it in a demo