


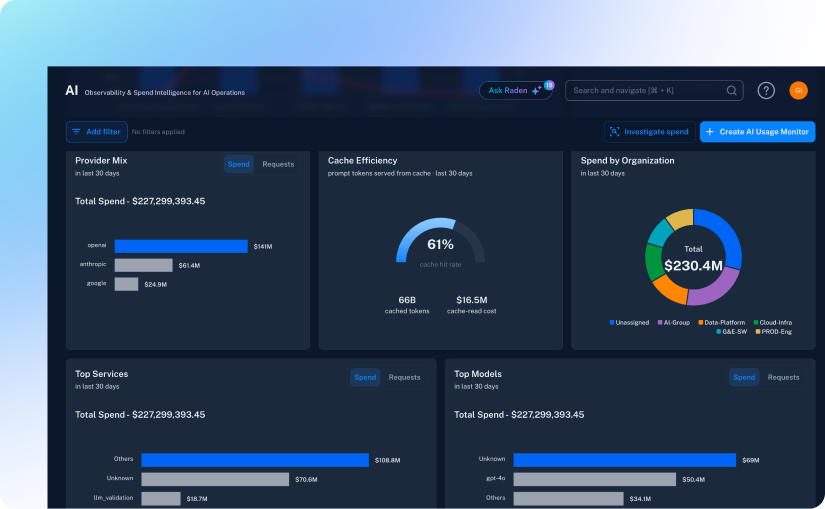
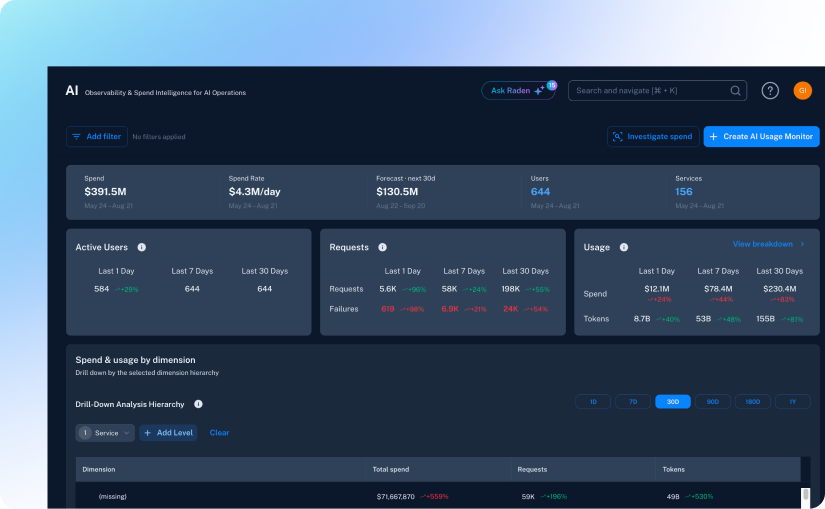
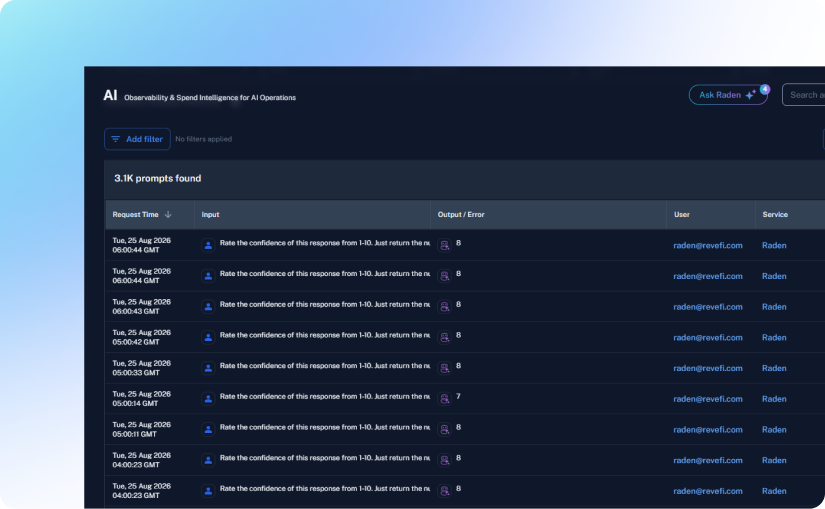
It is visibility into what each AI agent costs, how fast it runs, where it fails and how many tokens it uses across models and workflows.
Cost per run, latency, failures and token use, attributed from user to agent to model.
Hard and soft caps are enforced at runtime through the Revefi AI gateway or your own. Approval workflows handle exceptions and anomaly detection flags loops as they start.
Tracing shows what happened inside a run. Revefi adds cost attribution, spend controls and the data platform behind each agent.
OpenAI, Anthropic, Google, Amazon Bedrock and Azure OpenAI. Teams connect through the AI gateway, MCP server, SDK or direct API integrations.
See Revefi on your own stack in a demo, or estimate your savings first with our calculators for Snowflake, Databricks, Google BigQuery and AI.